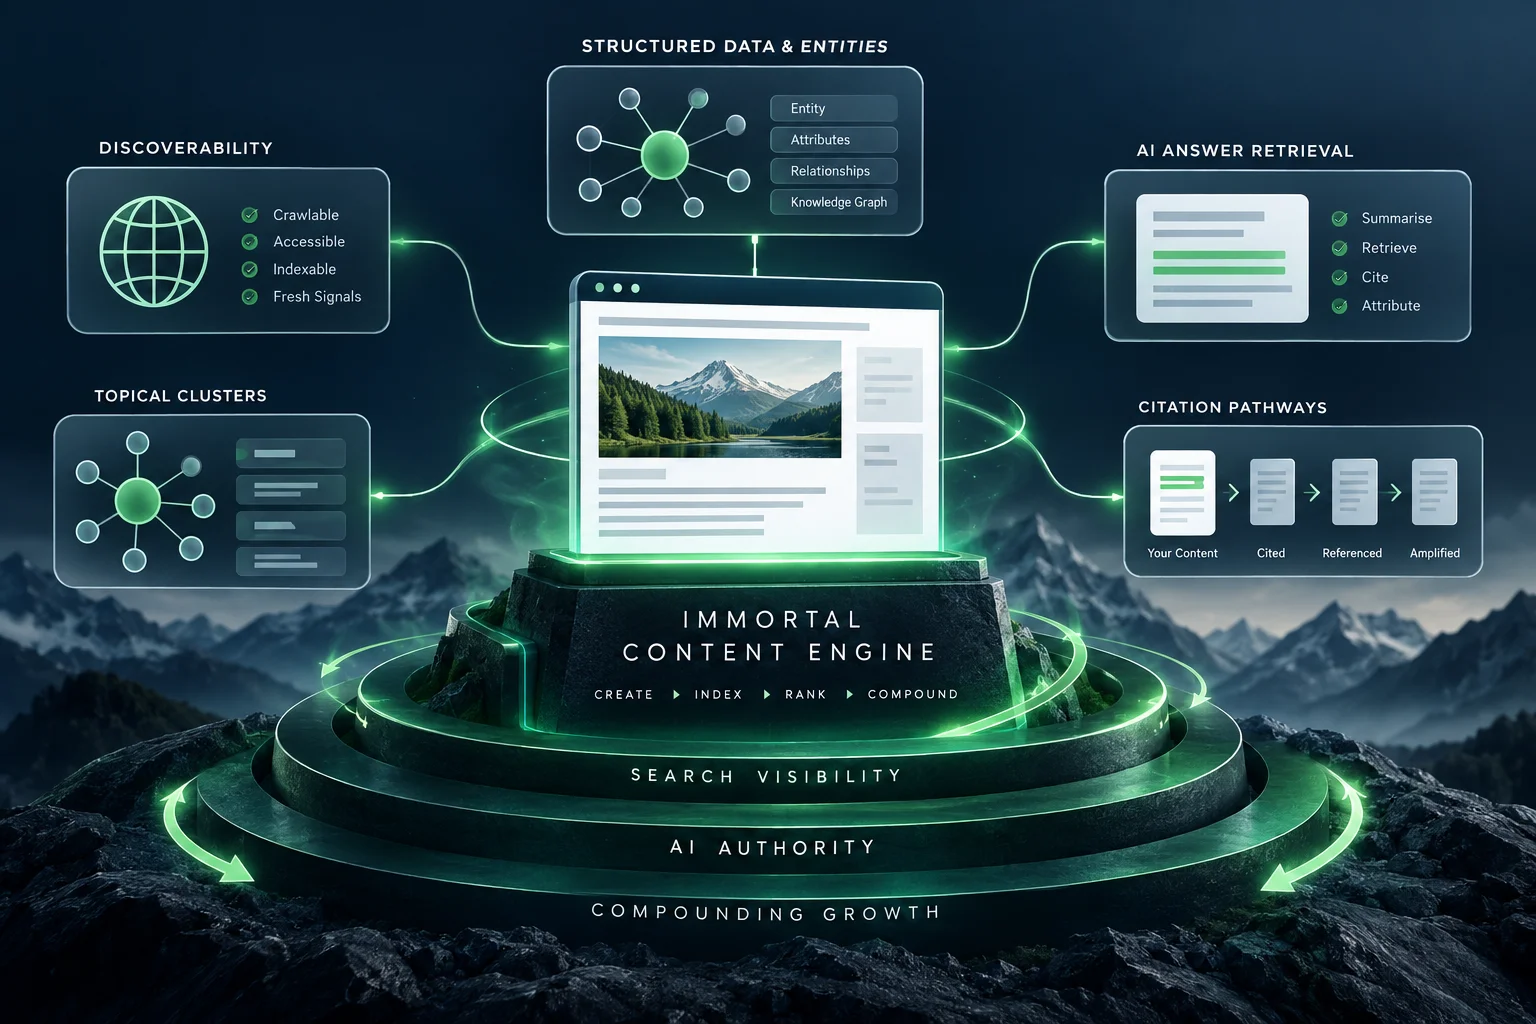
The Immortal Content Engine: Building Compounding Search and AI Authority
A practical, evidence-led blueprint for creating an immortal content engine that compounds search and AI visibility by combining entity architecture, structured data, internal linking, and measurement.
1. Why ‘Immortal Content’ and Compounding Authority Matter Now
Search and AI surfaces now prioritize entity understanding, concise answers, and authoritative summaries. For organizations that want durable visibility, isolated content production is inefficient—you need a system that compounds and reduces cost-to-serve over time.
What we mean by AEO, GEO and entities
AEO (answer engine optimization) focuses on how content surfaces in answer boxes and concise responses. GEO (generative engine optimization) focuses on visibility within generative AI outputs and summaries. An entity is a distinct thing with attributes (people, products, places, concepts). Search engines and modern AI use entity graphs and document-level signals to match concise, factual responses to queries. Treat AEO and GEO as optimization disciplines—their mechanics are testable and measurable but they are not guarantees of placement.
- AEO: optimize for direct answers, fact clarity, and attribution.
- GEO: optimize for synthesis, canonical sources, and reusable assets.
- Entity: canonical identifiers (names, types, attributes) and relationships are foundational.
Why compounding is a business KPI
Compounding authority reduces marginal cost-to-serve for recurring query classes. A well-architected content engine increases reuse: one authoritative entity page can be cited, summarized, and linked to from many derivative answers. Over time this lowers ongoing production cost and improves containment—the percentage of queries answered without high-effort escalation.
- Containment quality: percent of user needs satisfied by owned assets.
- Escalation quality: when escalation is necessary, routed assets and playbooks shorten resolution.
- Cost-to-serve: measure content production and maintenance versus queries contained.
2. The Operating Model: From Research to Iteration
Design an operating model that codifies how content becomes infrastructure. Peak Demand recommends this pipeline: research & entity model → topic & page graph → authoritative content → structured data & internal linking → distribution and brand signals → retrieval & citation surfaces → measurement & iteration.
Research and entity model
Start by mapping entities (products, services, people, locations, concepts) and their relationships. Research should combine query intent classification, SERP/AI-surface observation, and stakeholder domain knowledge. The entity model becomes the canonical source of truth for labels, synonyms, attributes, and priority intents.
- Create an entity registry with canonical names, types, IDs, and authoritative attributes.
- Map high‑value intents to entities and existing assets.
- Treat the entity model as living data maintained by content, product, and taxonomy owners.
Topic & page graph
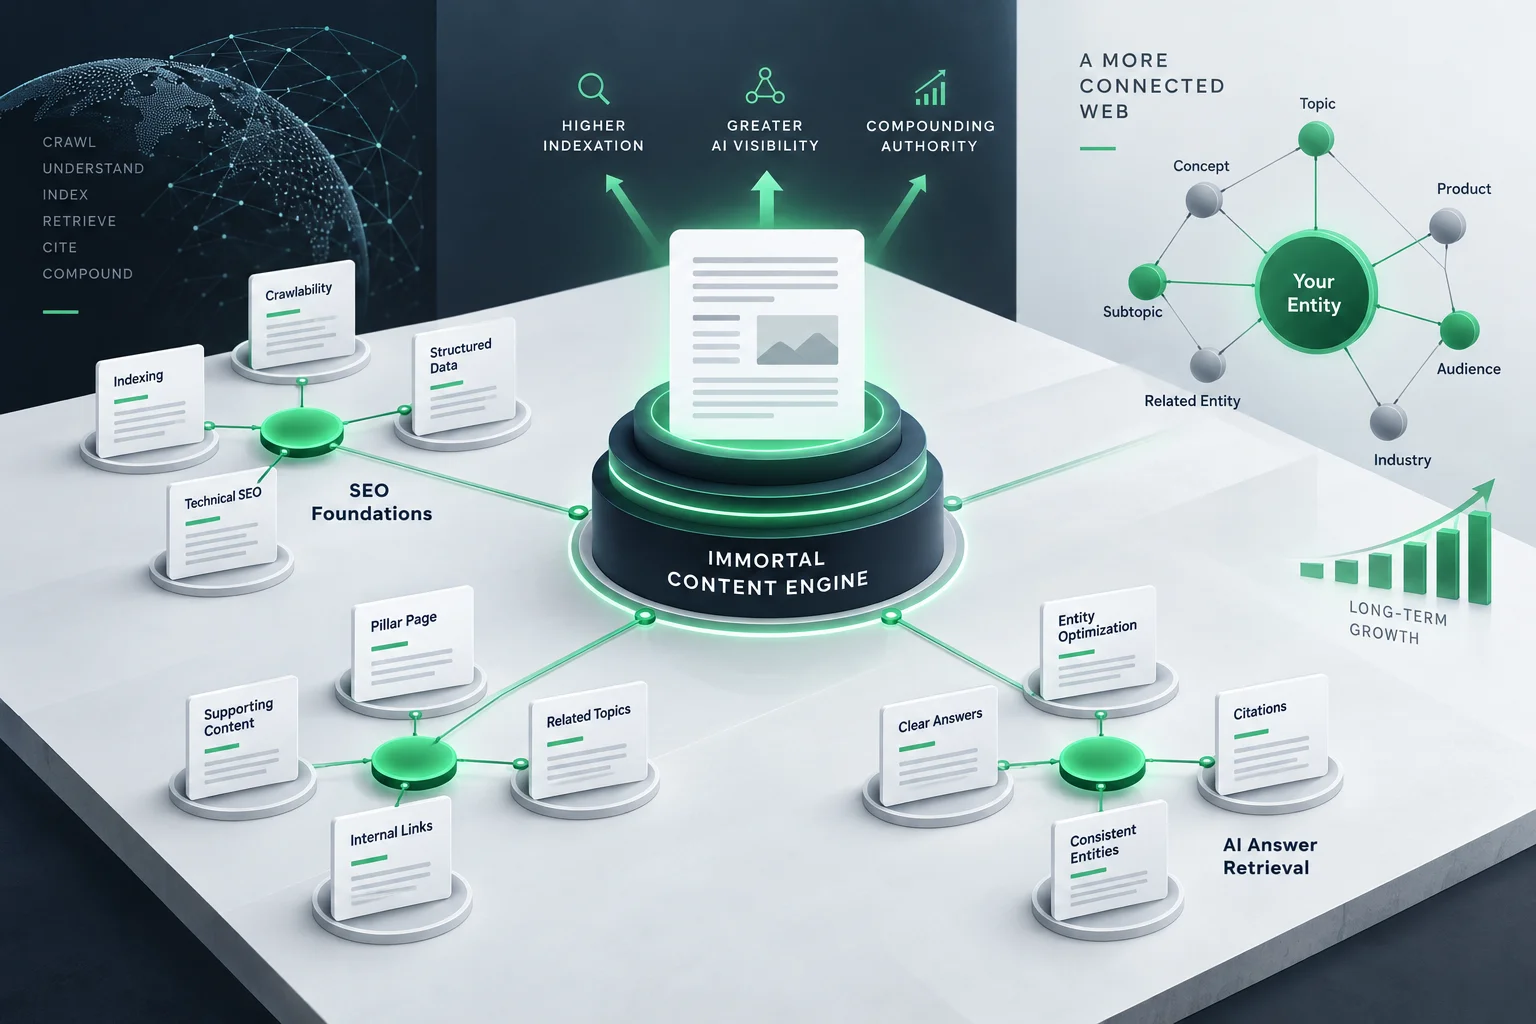
Design a page graph where each page serves an explicit node in the topic model: entity pages, pillar pages, explanation pages, procedural pages, and FAQ/intent pages. This graph supports reuse (quotes, stats, structured fields) and clear internal linking patterns to signal topical authority.
- Prefer single-purpose pages with clear intent alignment.
- Use canonicalization to prevent dilution across similar entity pages.
- Document linking rules: parent → child → related, and required anchor text patterns.
3. Content: Authoritativeness, People‑First Guidance, and QA
Content must be accurate, people‑first, updatable, and instrumented for reuse. Follow documented search guidance for helpful, reliable content while adding enterprise QA and change‑control workflows.
People‑first and helpful content
Google’s guidance on helpful, people‑first content emphasizes expertise, trustworthiness, and answering real user needs. Operationalize that guidance into editorial briefs, source requirements, and mandatory evidence capture for factual claims.
- Editorial briefs map intent to answer format (short answer, how‑to, comparison, deep explainer).
- Require source attribution and date/version metadata for factual or time‑sensitive claims.
- Maintain a change log and review cadence for entity pages.
Quality assurance and containment playbooks
Define QA gates: factual review, legal/privacy review where needed, accessibility check, and query-containment testing. Containment testing uses sampled query sets to measure whether owned assets answer queries without handoffs.
- Containment quality metric: percent of sampled queries resolved by owned content.
- Escalation paths: content update, new asset creation, or routing to human support.
- Cost-to-serve tracking: track time and dollars per resolved query class.
4. Technical Foundation: Schema, Machine‑Readable Signals, and Retrieval
Machine-readable SEO and structured data make entity attributes explicit to retrieval systems. They improve the precision of extractable facts, but do not guarantee AI citations or inclusion in summary features.
Structured data and schema strategy
Use schema.org structured data to expose entities, relationships, and key attributes in a machine-readable way. Structured data helps search engines and downstream models understand the role of each page and what facts are authoritative. Treat schema as part of the canonical asset, versioned with content.
- Prioritize entity-level markup (Thing types, Product, Organization, Person, FAQ, HowTo, Dataset) where appropriate.
- Expose attributes that match user intents: price, openingHours, steps, serviceArea, and authoritative contact points.
- Keep structured data accurate and consistent with visible content.
Machine‑readable SEO for scale
At enterprise scale, embed machine‑readable metadata consistently via templates, CMS fields, and a central metadata service. Peak Demand operationalizes this through machine‑readable SEO services that centralize schema generation, entity IDs, and internal linking rules to ensure consistency across thousands of pages.
- Template-driven schema generation reduces manual errors and improves auditability.
- Surface entity IDs in HTML and JSON‑LD for cross‑system interoperability.
- Audit pipelines to compare visible content with structured data.
5. Internal Linking, Citations and Retrieval Mechanics
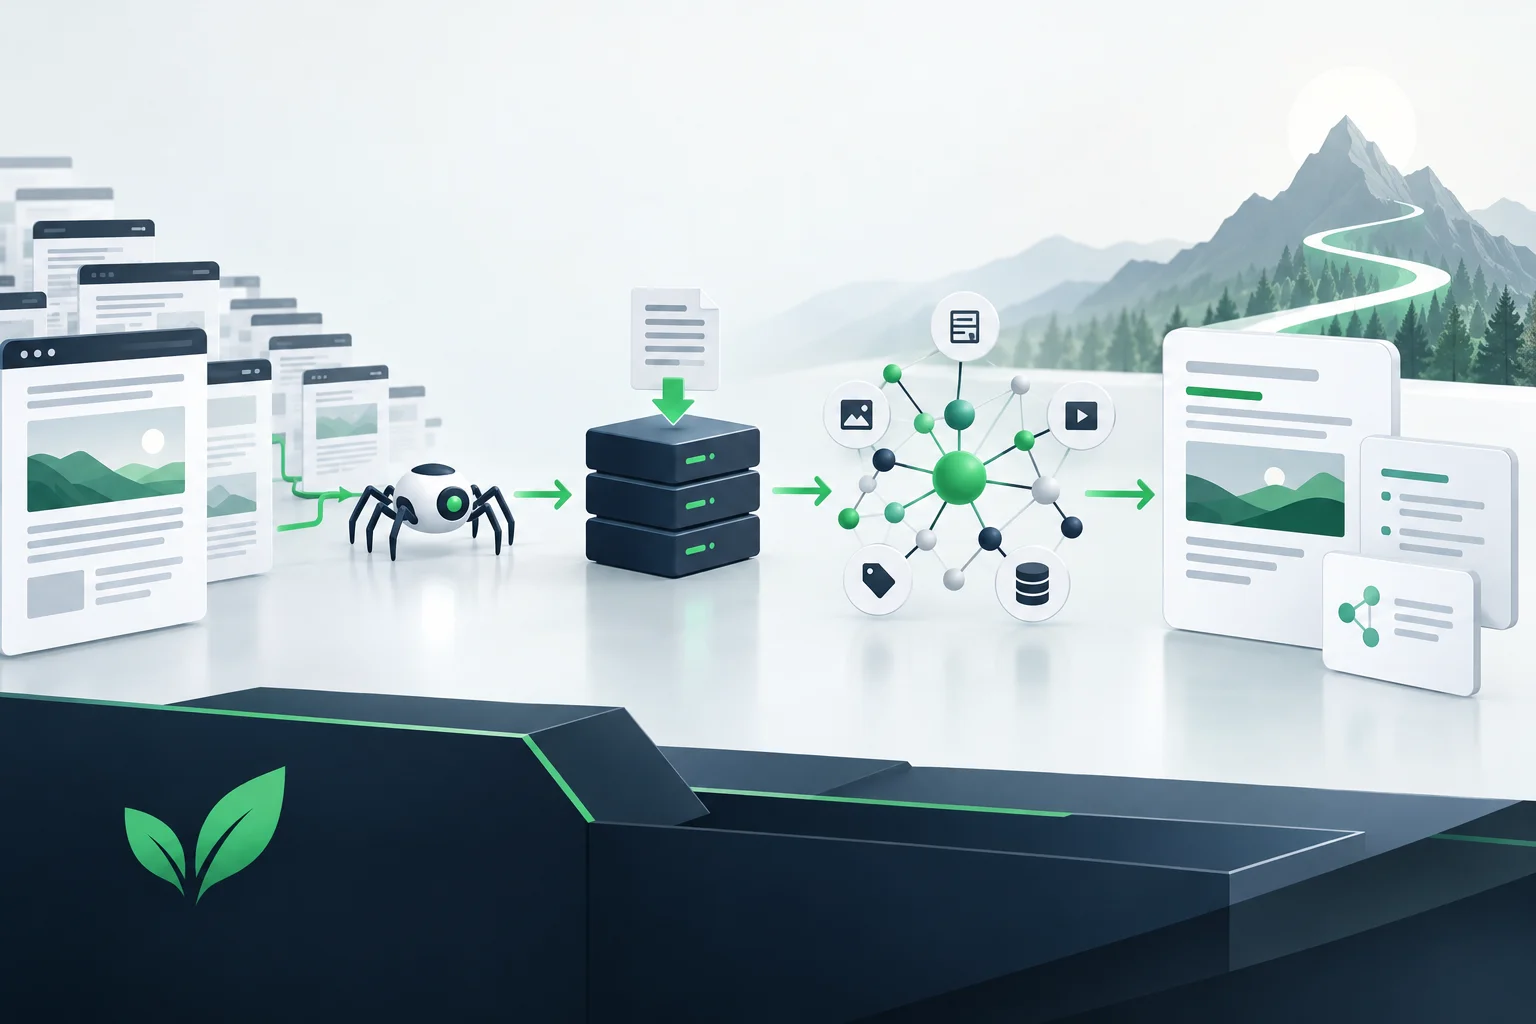
Internal linking and external citations shape retrieval signals. For AEO/GEO, retrieval systems look for authoritative source signals, freshness, and clarity of fact. Design linking and citation patterns to support retrieval and downstream summarization.
Linking rules that signal topical authority
Use predictable, programmatic linking patterns from pillar/entity pages to intent pages. Include contextual anchors that match the most common user phrasing for the intent. Avoid diluted or promotional anchor text; prefer descriptive and intent-aligned text.
- Parent entity pages should link to canonical intent pages and vice‑versa.
- Use rel=canonical, consistent hreflang, and pagination where needed to avoid fragmentation.
- Track inbound internal links per entity to prioritize maintenance.
Citations, provenance and retrieval
AI and search systems value explicit provenance. Where possible, expose source metadata (author, date, primary source links) and make the primary, canonical asset easily retrievable (short URL, stable schema, published date). However, structured signals increase the chance of retrieval without promising citation or LLM mention.
- Expose canonical source links in content and structured data.
- Prefer single canonical sources for facts to reduce contradictory signals.
- Log and monitor retrieval events where API access to AI features is available; correlate impressions with content fields.
6. Measurement, QA Metrics and Operational KPIs
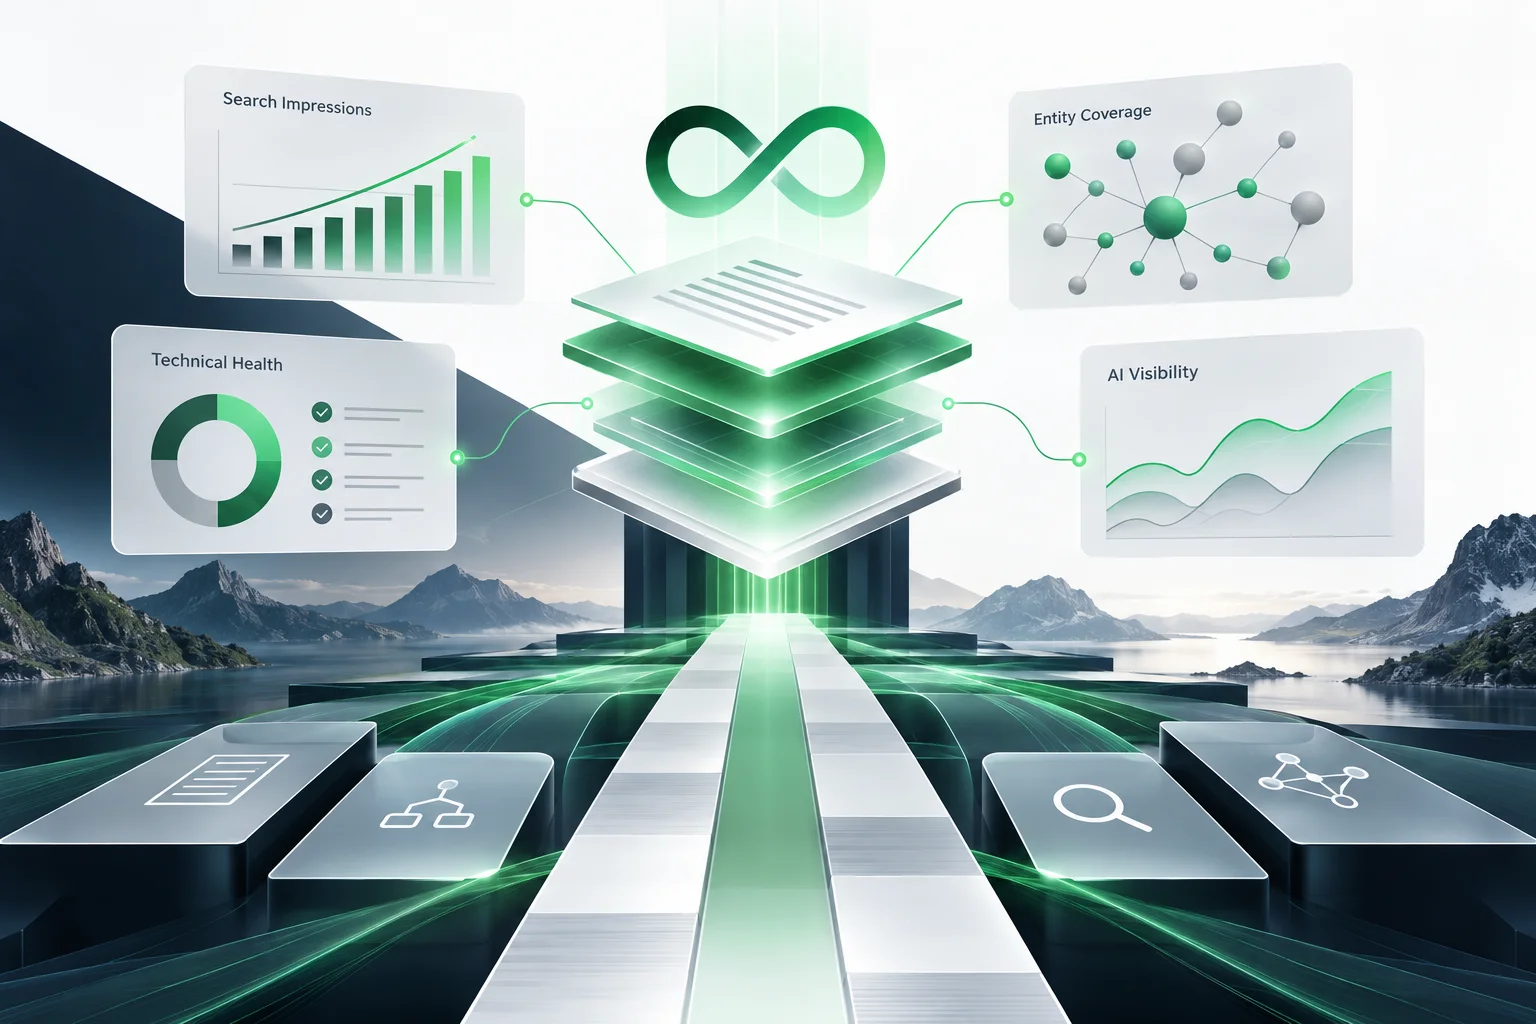
Measure more than rankings. For AEO/GEO success and operational health, track containment quality, escalation quality, cost-to-serve, retrieval coverage, multilingual parity, and per‑entity attribution.
Core measurement set
At minimum, maintain these KPIs and tests: containment rate, escalation rate/time, cost-to-serve per intent class, retrieval coverage (how often assets are surfaced by APIs or search features), and content freshness index. Combine search console, server logs, analytics, and API telemetry for a composite view.
- Containment rate = resolved queries by owned assets / sampled queries.
- Escalation quality = time-to-resolution and first-contact success for escalated queries.
- Cost-to-serve = production/maintenance spend divided by contained query volume.
Multi-site, multilingual and scale testing
For multi-site or multilingual deployments, measure parity of entity coverage and content quality across locales. Track hreflang and canonical correctness, and pipeline translation quality controls. Use A/B and canary testing for major structural changes to avoid systemic regressions.
- Locale parity checks: entity coverage, structured data parity, linked resources.
- Translation QA must include factual verification and date/version checks.
- Run regression tests on retrieval signals after template or schema updates.
7. Governance, Tools, and Continuous Optimization
Sustainability comes from governance: roles, playbooks, tooling, and an iterative cadence. Build guardrails and automation so the engine compounds without constant manual firefighting.
Roles and cadence
Define clear ownership: entity stewards, content owners, schema engineers, and retrieval analysts. Set an iteration cadence: weekly ingestion of query signals, monthly QA passes for high-value entities, and quarterly strategic reviews.
- Entity steward: maintains canonical data and attribute accuracy.
- Schema engineer: owns machine-readable templates and deployment.
- Retrieval analyst: monitors API/surface telemetry and runs containment tests.
Tooling and automation
Invest in scaled tooling: template engines for schema, validation pipelines, audit dashboards, and automated regression tests. Peak Demand’s Machine‑Readable SEO Services centralize schema generation, validation and internal linking rules so teams can deploy consistent, auditable structured data at scale.
- Validation pipelines: compare visible content to JSON‑LD and flag mismatches.
- Audit dashboards: entity coverage, degraded pages, and retrieval exposure.
- Automation for routine updates: price, availability, or seasonal changes.
Related Peak Demand resources
Industry and AI sources reviewed
- Creating helpful, reliable, people-first contentGoogle Search Central
- Understand how structured data worksGoogle Search Central
- Schema.org DocumentationSchema.org
- AI features and your websiteGoogle Search Central
- SEO Starter GuideGoogle Search Central
Search-engine and AI-answer behavior changes over time. Google documentation can establish published requirements and guidance, but inclusion in rankings, AI Overviews, citations, or LLM answers is never guaranteed. Practitioner observations should be labelled as inference or testing rather than official ranking factors. This article is operational guidance, not legal advice; organizations should confirm applicable requirements with qualified professionals.
Frequently asked questions
SEO improves visibility in traditional search results. AEO focuses on making content easy for answer systems to extract and use. GEO focuses on visibility in generative search and AI answer experiences. In practice, the strongest strategy combines technical accessibility, useful content, clear entities, strong internal relationships, structured data, and credible source authority rather than treating them as isolated channels.
Official reference: SEO Starter Guide
No. Structured data can make page entities and relationships more explicit and can support eligible search features, but it does not guarantee rankings, AI Overview inclusion, citations, or mentions in generative answers. It should reinforce accurate visible content rather than replace it.
Official reference: Understand how structured data works
Search and answer systems need to understand what a brand, person, product, service, or concept is and how it relates to other entities. Consistent naming, authoritative pages, structured relationships, internal linking, and corroborating references can reduce ambiguity and make a site easier to interpret and retrieve.
Official reference: Schema.org Documentation
Track traditional search visibility alongside query coverage, indexed pages, non-brand discovery, AI referral traffic where available, observed citations or mentions, entity consistency, content-cluster coverage, internal-link depth, and lead quality. Treat AI-surface monitoring as directional because answer composition can vary by model, query, user, and time.
Official reference: AI features and your website
Build a search and AI visibility system that compounds
Peak Demand connects technical SEO, entity architecture, knowledge graphs, structured data, topical authority, internal linking, distribution, and measurement into a managed SEO/AEO/GEO operating system.
Explore Peak Demand AI SEO, AEO & GEO


