Regulatory Capital Planning for Utility Voice AI: Rate‑Case Evidence & Controls
A practical, jurisdiction‑neutral framework to justify utility Voice AI capital investments in rate cases: operational architecture, integration and validation controls, outage safeguards, procurement evidence, and measurable audit trails.
1. Scope, audience, and regulatory framing
Explain what the rate‑case request covers, who benefits, and the operational guardrails that separate capitalized components from ongoing operating costs.
Purpose and covered capabilities
For a regulator to consider capital, provide an explicit list of deliverables: platform licensing or build, integration adapters to approved systems (CIS/OMS/CRM/work-order systems), secure hosting provisioned by region, initial configuration, and automated routing workflows that create service-requests or status updates. Exclude routine tuning, model updates, and transcript storage costs unless your accounting practice capitalizes them. Present the capability as improving service availability, scalability, and auditability for high-volume customer interactions.
- Platform or platform‑engineering work (capital)
- System adapters and approved API integrations (capital)
- Initial QA, acceptance testing, and deployment (capital)
- Operational model updates, transcription review, and day‑to‑day monitoring (typically O&M unless policy differs)
Audience and decision criteria
Target the evidence at regulators, commission staff, and internal rate-case teams. Use operational language: containment (calls resolved without agent), escalation fidelity (correct handoffs), outage notification accuracy, and integration reliability. Avoid technical marketing claims—connect capabilities to customer outcomes, reduced wait times, and auditable process improvements. Include a summary of controls that ensure the system is a communications and routing tool, not an operational controller.
- Operational leaders (call centre, field service, outage comms) need routing and escalation metrics.
- IT and security assess hosting, data transfer, and subprocessors.
- Regulatory teams need acceptance tests, cost allocation, and audit trails.
2. Rate‑case evidence: what convinces regulators
Regulators need reproducible, measurable evidence tying the capital investment to reliable, auditable service improvements and risk mitigation.
Quantitative acceptance tests and datasets
Provide a testing plan with representative call datasets (redacted or synthetic) and clear pass/fail criteria. Acceptance tests should run across the operational envelope: peak concurrency, multi‑language prompts, outage scenarios, and degraded upstream system access. Define tests for containment (correctly completed transactions), safe‑fail behavior (where the system must escalate or provide human fallback), and routing accuracy. Deliver test artifacts: transcripts, decision traces, and API call logs for the test window.
- Representative test corpus (peak/off‑peak, outage v normal requests)
- Containment and escalation pass thresholds defined in plain language
- Recordings and decision logs retained for audit
O&M vs capital allocation rationale
Explain the accounting boundary: capital covers the hardened engineering of the platform, adapters, and initial deployment. Operational expenses cover voice model maintenance, content updates, and monitoring staffing. For regulators, document resource depreciation, expected useful life, and upgrade cycles. Where hybrid procurement (managed service) is used, present componentized costs—platform, integrations, and managed‑service hours—so regulators can approve capital where justified.
- Itemize one‑time engineering and integration costs
- Describe recurring platform and managed‑service fees separately
- Provide depreciation assumptions and upgrade cadence
3. Operational architecture and integration controls
A concise operational architecture is necessary for technical reviewers. The canonical flow demonstrates where controls and evidence live.
Canonical call flow and decision boundaries
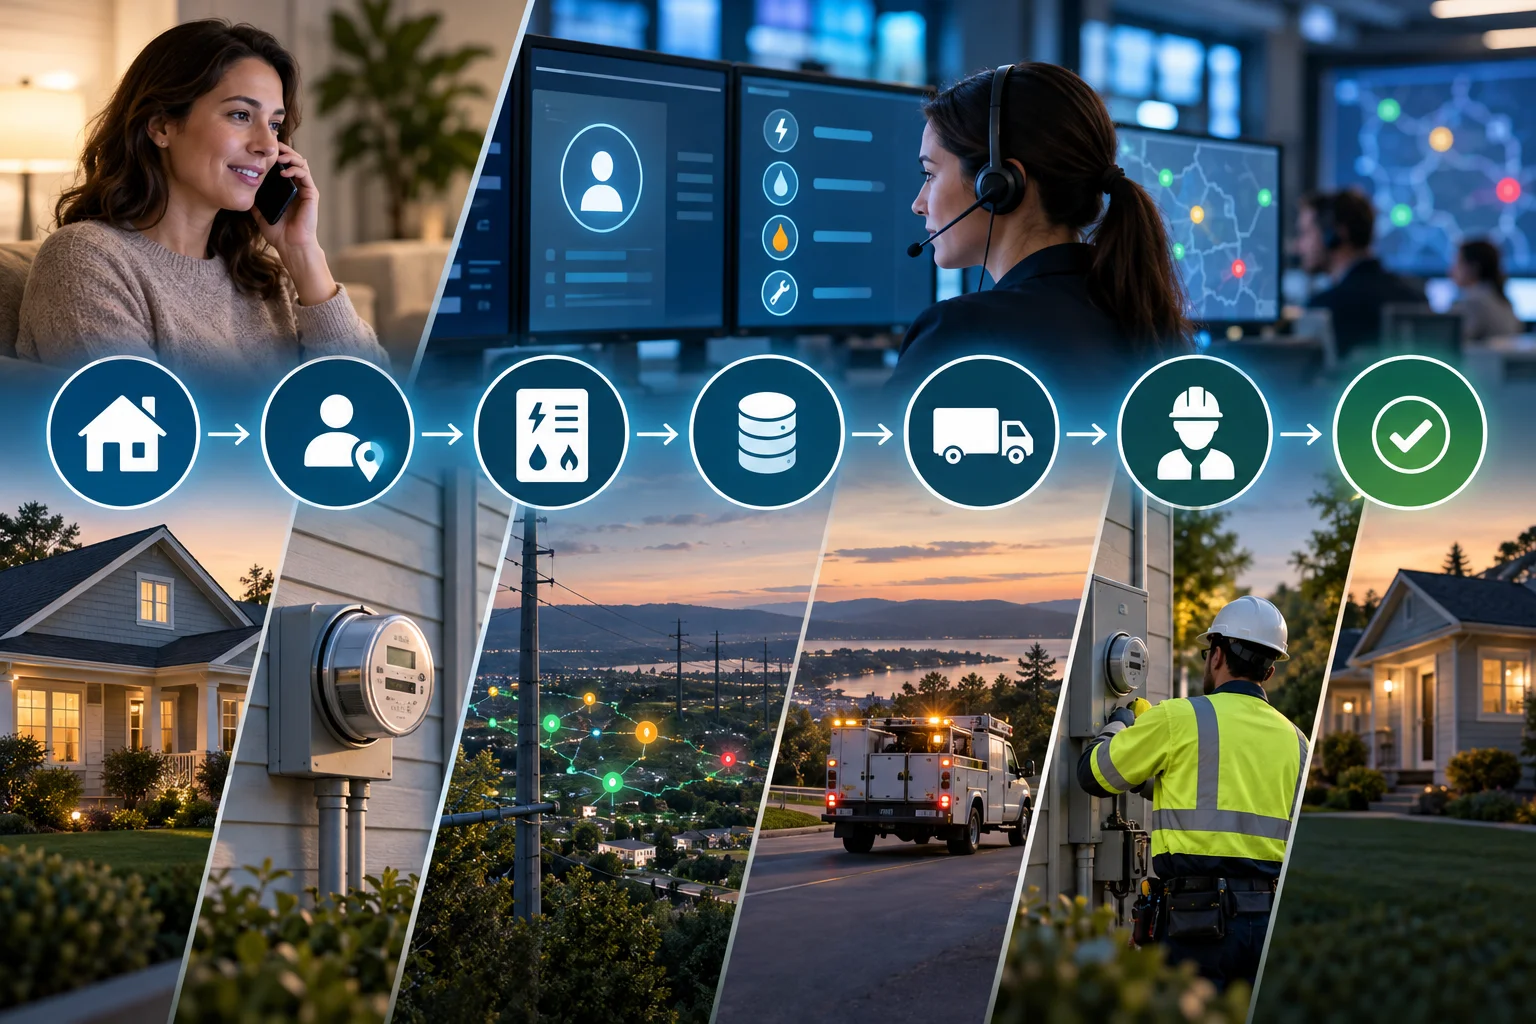
Document the canonical sequence: Caller → Interactive Voice Response / Telephony → Voice AI (intent classification and slot filling) → Account/location validation via approved APIs → Decision node: (A) create service request in OMS/CIS; (B) return status from CRM/Knowledge source; or (C) escalate to human agent. Explicitly mark safety and operational boundaries: Voice AI supplies communications and data lookup; it does not issue work orders that change field operations without human confirmation.
- Validate identity/premise via approved, auditable APIs prior to account‑specific disclosures
- Use controlled adapters for OMS/CIS/CRM writes with pre‑write confirmation steps
- Log every decision with request ID, intent, confidence score, and downstream API outcome
Integration adapters, adapters testing and approvals
Integrations must be implemented as controlled adapters with versioning and test harnesses. Provide a matrix showing each integration, access method, remote‑call schema, error modes, retry rules, and circuit‑breaker thresholds. For rate-case evidence, include an integration readiness report and runbook that shows how failures are detected and how human fallback is invoked.
- Adapter version, supported API specs, and change control record
- Error classification: transient, persistent, degraded-data, and authentication
- Circuit‑breaker and retry behavior with thresholds documented
4. Reliability, human escalation, and outage safeguards
Outage communications and field‑service requests demand conservative failure modes and auditable human oversight.
Human‑in‑loop escalation and failure boundaries
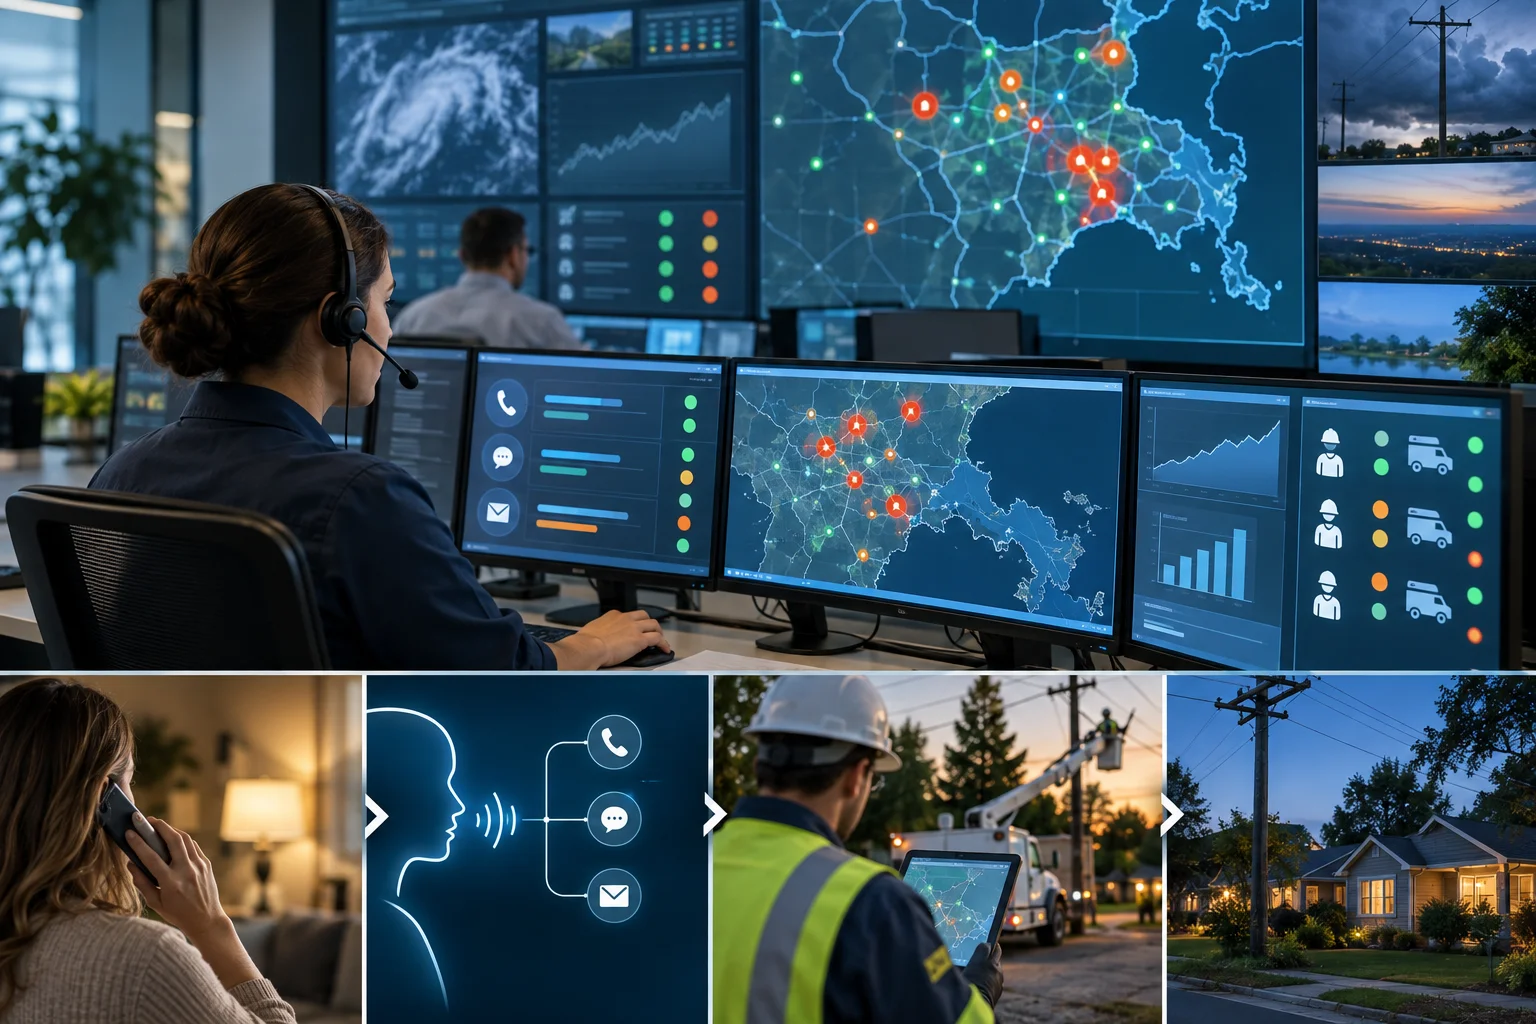
Design escalation as mandatory for low‑confidence intents, safety‑relevant keywords, ambiguous account validation, or when prescribed by outage playbooks. Escalation should include a structured handoff: the Voice AI places the interaction in a queue with metadata (confidence, transcripts, validation steps taken), and the agent sees the same decision trace before taking action. For rate‑case evidence, supply a handoff transcript sample, the agent interface mockup, and ruleset showing when automation is disallowed.
- Mandatory escalation triggers (confidence thresholds, specific keywords, validation failures)
- Handoff package contains decision trace, confidence, and relevant API responses
- Escalation latency SLAs and monitoring
Outage messaging and non‑control assurance
Voice AI may deliver outage notifications, estimated restoration times, and status updates, but must never assert actions to manipulate physical infrastructure. Build conservative templates: clearly label estimated times as provisional, provide human verification steps for service‑restoration confirmations, and require agent sign‑off before publishing any operational directive. Provide regulators with sample outage flows, templates, and the human verification step that prevents misleading or unsafe communications.
- Templates with explicit provisional language and verification gates
- Requirements for human confirmation before posting restoration claims
- Record retention for outage notifications and follow‑up audits
5. Cybersecurity, data residency, and continuity controls
Capitalized elements should include the engineering and configuration needed to meet security and continuity expectations; map these to established performance goals and maturity models in evidence packages.
Mapping to cybersecurity and resilience goals
Show how the implementation aligns with cross‑sector cybersecurity objectives—identity and access control, least privilege for adapters, encryption at rest and in transit, and secure remote‑support controls. Use maturity profiling to demonstrate intent: a concise mapping of implemented controls to the CISA Cross‑Sector Cybersecurity Performance Goals and DOE C2M2 maturity elements strengthens the capital request by showing engineering rigor and risk reduction.
- Document identity and access model for system components and subprocessors
- Describe encryption, key management, and logging retention
- Provide a maturity mapping to CISA CPGs and DOE C2M2 where applicable
Hosting, backup, subprocessors and remote support
Provide network diagrams showing primary hosting region, backup region, and designated subprocessors. For capital evidence, include the engineered high‑availability design, data replication plan, and remote‑support controls (who can access systems, under what approval, and audit trails of sessions). Document cross‑border transfer mechanisms, retention policies for recordings and logs, and the procedures for breach notification. State applicable jurisdictional limits and recommend that utilities confirm legal obligations with qualified counsel.
- Primary and secondary hosting regions, backup geography, and RTO/RPO expectations
- List of subprocessors and the mechanism for onward transfer governance
- Remote‑support access controls with session recording and approvals
6. Procurement, acceptance, and evidentiary playbook
Regulators look for concrete contractual language, acceptance tests, and the ability to audit performance post‑deployment.
Contract clauses and SLA structure
Recommended contract items: a componentized Statement of Work that distinguishes capital deliverables from managed services; SLAs for platform availability, integration success rate, and escalation latency; defined remedies and outage credits tied to testable metrics; and clauses requiring exportable logs for regulator or third‑party audits. Include change‑control procedures and vendor obligations for subprocessors and data residency.
- Componentized SOW with deliverable acceptance criteria
- SLAs on integration success, escalation latency, and availability
- Audit rights, log export formats, and breach notification timing
Acceptance testing and audit artifacts
Acceptance should be tied to the quantitative tests described earlier with signed artifacts: test results, sample transcripts, system logs, and a post‑deployment runbook. Prepare an independent verification routine—either by internal QA or an approved third party—to run a subset of tests periodically, and provide a schedule for submission of results to the commission as part of performance reporting.
- Signed acceptance certificates with test artifact attachments
- Periodic independent verification schedule
- Requirement for ongoing reporting of defined KPIs to regulators
7. Measurement, governance, and continual improvement
An ongoing governance program with clear KPIs and QA cycles is essential for regulatory trust and operational reliability.
KPIs, dashboards, and measurable outcomes
Define a small set of regulator‑facing KPIs and internal operational metrics: containment and escalation rates, correct‑routing rate (verified against sampled transcripts), time‑to‑escalate, failed‑validation rate, and incident response times for integration failures. Provide examples of dashboards and the underlying event‑level analytics that tie voice interactions to ticket creation and field closure events; these are the primary audit links between the investment and its claimed service improvements.
- Regulatory KPIs: containment, correct‑routing, escalations with root cause breakdowns
- Operational KPIs: integration error rate, latency, and verification sampling results
- Event‑level analytics that link calls to OMS/CIS/field outcomes
QA cadence, change control and incident response
Present a documented QA and change‑control cadence: quarterly governance reviews, monthly QA sampling, and incident response playbooks for integration or security events. For incidents that affect customer communications (e.g., incorrect outage notifications), have a predefined rollback procedure and public communications template. Link these governance artifacts to the acceptance criteria so post‑deployment performance is auditable.
- Scheduled QA sampling and governance review calendar
- Incident response playbook specific to voice‑driven customer communications
- Rollback and public communications templates
Related Peak Demand resources
Industry and AI sources reviewed
- AI Risk Management Framework — Critical Infrastructure ProfileNational Institute of Standards and Technology (NIST)
- Cross-Sector Cybersecurity Performance GoalsCybersecurity and Infrastructure Security Agency (CISA)
- Cybersecurity Capability Maturity Model (C2M2)U.S. Department of Energy
Utility cybersecurity, critical-infrastructure, records, customer-protection, and emergency-communications obligations vary by jurisdiction and service type. This article is operational guidance, not legal advice; organizations should confirm applicable requirements with qualified professionals.
Frequently asked questions
Good starting points include billing and account questions, move-in or move-out intake, appointment scheduling, service-request capture, outage-status messaging from approved systems, payment-routing assistance, and structured escalation. Safety-critical and infrastructure-control decisions should remain with qualified utility teams.
Official reference: Cross-Sector Cybersecurity Performance Goals
Use the minimum approved identifiers needed for the workflow, validate them against the utility's system of record, limit data exposure, and provide a human-assisted path when verification fails. The Voice AI should not guess account, premise, or outage information.
Official reference: Cross-Sector Cybersecurity Performance Goals
Use controlled adapters, strict schemas, timeouts, retries, audit logs, safe failure states, and human escalation. The system should distinguish approved utility data from model-generated language and should never present stale or unverified operational information as fact.
Official reference: Cybersecurity Capability Maturity Model (C2M2)
Track containment by request type, successful validations, transfers, abandoned calls, integration errors, incorrect or stale responses, time to resolution, customer follow-up, and the percentage of cases completed safely without manual rework.
Official reference: Cybersecurity Capability Maturity Model (C2M2)
Build resilient utility customer-service automation
Peak Demand helps utilities connect Voice AI to approved customer-information, outage-communication, service-request, dispatch, escalation, and analytics workflows.
Schedule a discovery call


