Voice AI Portfolio Governance: SLO‑Driven Funding, Decommissioning, and Risk Controls
A decision-focused guide for enterprise leaders: using service-level objectives to fund, scale, retire and control Voice AI across contact‑centre portfolios. Includes architecture, procurement checklists, failure boundaries and operational controls.
1. Why SLO‑Driven Governance Matters for Voice AI
Enterprises must move beyond feature pilots to disciplined portfolio governance. SLOs are the single most practical tool to align procurement, risk, operations and platform teams around measurable business and safety outcomes.
SLOs as funding and risk levers
Treat each Voice AI capability (IVR replacement, payments, order status, agent augmentation) as a service with a small set of SLOs. Use these SLOs to decide whether to fund scale, keep as managed experiment, or retire. Typical SLOs include successful intent resolution rate, authorized-transaction completion rate, average complete time, user‑reported escalation rate, and human‑handoff latency. Funding decisions should be explicit: e.g., rollout to 10% traffic pending 95% intent-success and <2% failed verification within 90 days.
- Portfolio SLO (business): intent-success weighted by contact value.
- Application SLO (operational): latency, error, human-handoff time.
- Safety SLO: critical-failure rate, unauthorized action rate.
Aligning stakeholders with SLOs
SLOs create a cross-functional contract: CX and operations measure experience; IT and security measure controls and observability; procurement ties commercial terms and funding to SLO gates; transformation tracks adoption and cost‑benefit. Define who owns the SLO numerators and denominators and how SLOs are measured (production telemetry, QA replays, and post-call surveys).
- Designate SLO owners: platform, product, or vendor depending on the contract.
- Standardize measurement windows and sampling methods across the portfolio.
- Use SLOs for stage funding: pilot → supported deployment → enterprise scale.
2. Portfolio Architecture and Clear Ownership
A decision-useful architecture clarifies where operational risk and integration responsibilities live. Use the same canonical flow across projects so SLOs, measurement and controls are consistent.
Canonical architecture: caller to analytics
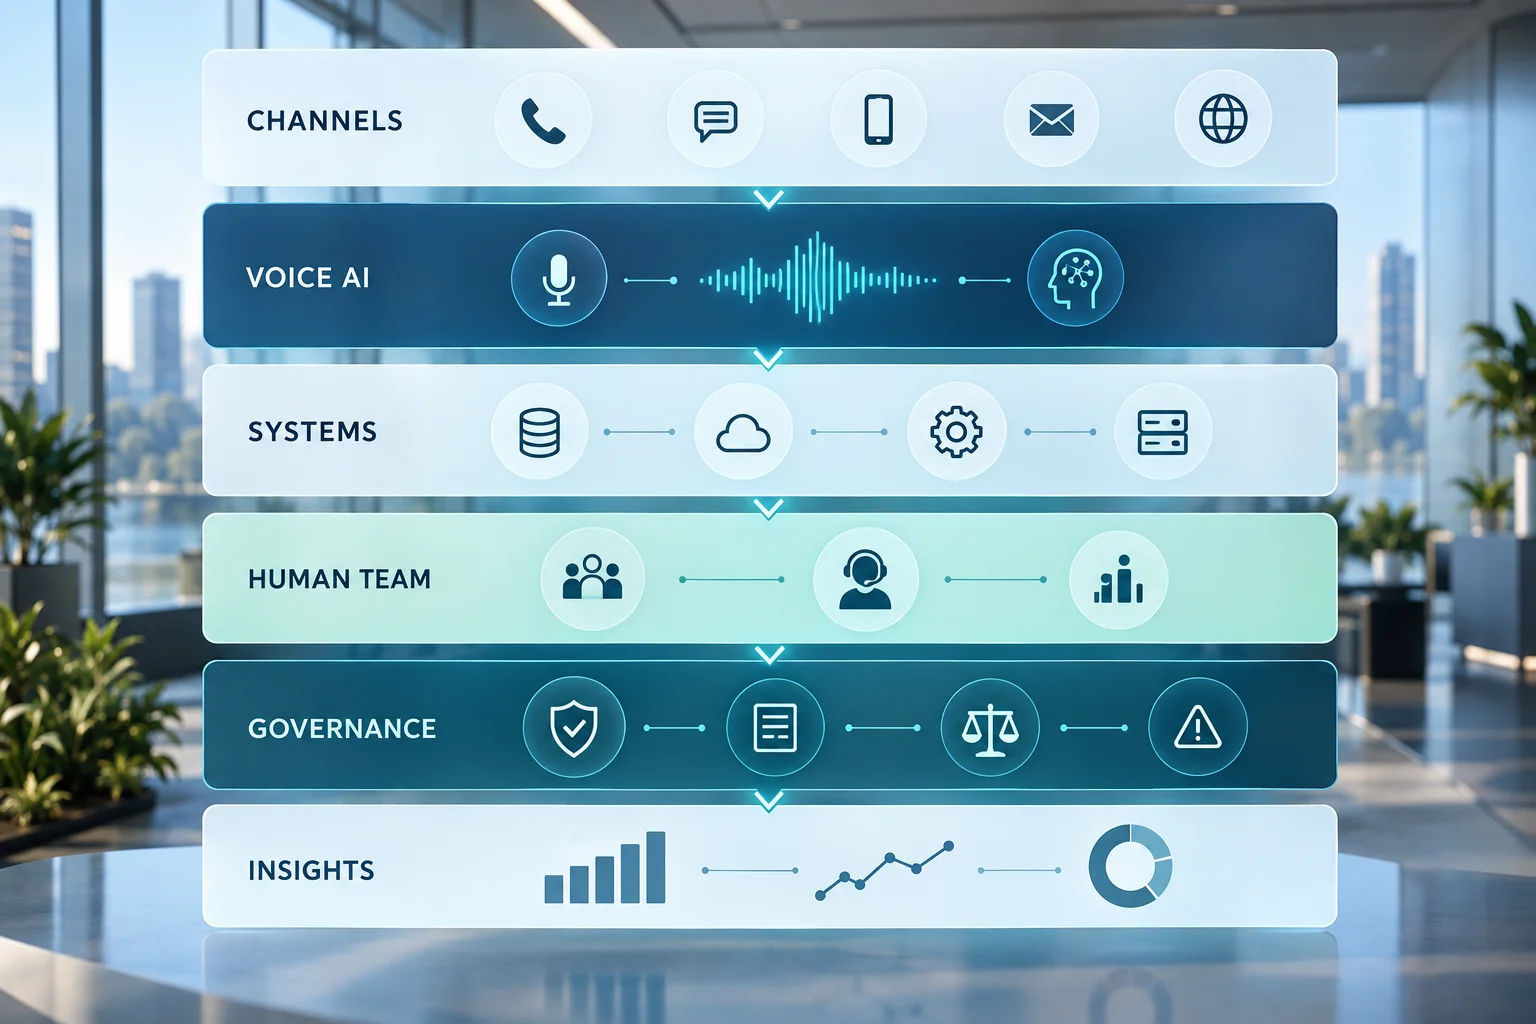
Adopt this end-to-end model: Caller → Voice AI (ASR/NLU/dialog) → business-rules layer (policies, validation, routing) → approved enterprise systems (CRM, billing, payment, fraud services) → response/transaction or human handoff → QA and analytics. Enforce approved API contracts and adapters for every external system. This separation lets you apply policy gates at the business-rules layer and ensures observability points at every transition.
- Instrument transition events: intent-detected, transaction-requested, handoff-initiated, recording-stored, and transaction-completed.
- Use controlled adapters for system calls, not direct model-driven writes.
- Require replayable traces and recorded transcripts for QA and audit.
Managed service versus in-house components
Decide what the vendor supplies and what the enterprise retains. Contracts should be explicit about custom infrastructure (hosting region, backup geography, subprocessors), logic bridges (business-rules layer), adapters/integrations, QA tooling, observability, and human escalation. Peak Demand’s managed-service guidance outlines the expected responsibilities and deliverables for each party.
- Vendor-managed: core Voice AI runtime, model updates, first-line monitoring (if contracted).
- Client-managed: enterprise systems, sensitive data stores, policy enforcement, final authorization decisions.
- Hybrid: vendor builds adapters and logic bridges, but customer retains approval and production keys for sensitive transactions.
Integration ownership and contractual clarity
Make integration ownership a procurement gating item. Who maintains adapters, handles schema changes, and owns retries? Require SLAs for adapter uptime, error rates, and API compatibility. Contracts should include an integration runbook, contact list, and escalation SLA for production incidents.
- Require vendor to provide tested adapters with versioning and compatibility matrices.
- Obligate vendors to support read-only test environments that mirror production.
- Include change-notice periods for schema or API updates and a rollback clause.
3. Funding, Stage Gates and SLO‑Driven Decommissioning
Funding should be conditional and measurable. Use SLO gates at stage boundaries and automated decommissioning rules to avoid sunk-cost escalation.
Stage-based funding model
Structure funding rounds by stage: Proof of Value (PoV), Controlled Rollout, Platform Integration, and Enterprise Scale. Each stage requires passing SLO gates and compliance checks (security review, human oversight, records retention). Tie incremental funding to evidence: production telemetry, QA replays, customer satisfaction, and five‑day operational readiness.
- PoV: limited traffic, basic SLOs, security smoke tests.
- Controlled Rollout: integration with CRM/OMS, human‑in‑loop, stricter SLOs.
- Platform Integration and Scale: full observability, backup geography, subprocessors approved.
SLO thresholds that trigger decommissioning
Define decommissioning triggers in procurement documents. Triggers should be objective, e.g., sustained failure to meet critical SLOs for a defined window (for example, 3 months at 90% confidence), unacceptable security incidents, or failed vendor audits. Decommissioning is a controlled process: traffic migration, data export, adapter disablement, final record retention and contractual termination steps.
- Escalation SLO breach → remediation window → temporary traffic rollback.
- Sustained breach past remediation → freeze on new feature funding and initiation of decommission runbook.
- Permanent failure → controlled cutover to fallback channel with retention and forensic data export.
Financial controls and re‑use of budgets
Use project‑level ledgers and chargeback for operations. When decommissioning, capture reusable artifacts: adapters, tested business rules, and QA suites. Require vendors to hand over runbooks, export scripts, and an assembly of observability dashboards to avoid vendor lock‑in.
- Budget tranches tied to passing SLOs and audit gates.
- Contractual handover package at termination (code, schemas, logs, runbooks).
- Retain tested adapters where feasible to reduce rebuild time.
4. Risk Controls, Human Oversight and Safety Boundaries
Voice AI systems operate in regulated and sensitive contexts. Embed safety boundaries and human oversight strategically to keep high‑risk decisions under human control.
Decision boundaries and escalation design
Map decisions by risk tier (informational, transactional, high-risk). Keep high‑risk actions—billing changes, credentialed information, clinical advice—behind explicit human approval. Implement deterministic policy checks in the business‑rules layer before any external system write or payment request.
- Tier 1 (Low risk): status queries, FAQs—automated with monitoring.
- Tier 2 (Moderate risk): account changes, sensitive lookups—require two-party verification or human review.
- Tier 3 (High risk): financial transactions, legal or clinical outcomes—always require final human approval.
Human-in-loop workflows and escalation SLAs
Design human‑in‑loop (HITL) so the agent or supervisor sees context-rich transcripts and structured state. Define escalation SLAs (e.g., <30s for live handoff, <5 min for callback in peak conditions) as part of SLOs. Ensure every human action is auditable, time-stamped and stored with the corresponding recording and metadata.
- Use a prioritized handoff queue with observable wait-time SLOs.
- Require agents to record reason codes for overrides and corrections.
- Keep a replayable transcript context for QA and forensic review.
Data handling, residency and transfer principles
Document hosting region, backup geography, subprocessors, remote-support access, retention policy, and recording consent. Treat these as part of the vendor evaluation and contract. Organizations must confirm jurisdictional obligations with qualified counsel because legal requirements vary by country.
- Specify data residency for production stores and backups.
- Require subprocessors list and transfer mechanisms for cross-border flows.
- Define retention, erasure and breach-notification responsibilities.
5. Operational Controls: QA, Observability and Change Management
Operational resilience depends on auditable QA, measurable observability and disciplined change control. These are not optional in regulated environments.
Observability and SLO telemetry
Instrument the system for SLOs and root-cause resolution: call trace IDs, intent confidence, ASR error rates, business-rule decision logs, adapter latencies, third-party API error rates, escalation events, and human override signals. Use synthetic tests, production samplers and replay systems that let QA validate model behaviour against known transcripts.
- Primary SLO metrics: success rate, escalation rate, P95 latency, adapter error rate.
- Supplement with change-sensitive metrics: model drift, increased fallback rate, repeated failures per caller.
- Keep a central SLO dashboard and automated alerting tied to incident response runbooks.
Change control, canary and rollback
Require a formal change-control process that includes model-versioning, canary rollouts, safety checks, and immediate rollback criteria. A release should include: test artifacts, QA approvals, security checklist, and an operational runbook. Define automatic rollback triggers (eg, sudden increase in escalation rate or production error rate).
- Canary on a small percentage of traffic with escalating checks.
- Gate full rollout on passing automated QA and live SLOs.
- Keep fast rollback and a documented fallback channel (human or IVR).
Auditable records and forensic readiness
Maintain immutable logs for decisions that affect customers. Record timestamps, versioned business rules, model identifier, adapters used, and human interventions. These records must be searchable and exportable to meet audit and forensic needs.
- Store call recordings and structured decision logs together for replay.
- Preserve change history for business rules and adapter versions.
- Define retention windows by business need and regulatory considerations.
6. Procurement and Vendor Selection Checklist
Ask vendors for concrete, testable deliverables. Avoid vague commitments—insist on artefacts that let you operate, audit and, if necessary, exit cleanly.
Minimum contractual items
Require clear delivery on: SLO definitions and measurement method; integration ownership and adapter code; observability and exportable SLO telemetry; human escalation tooling; security controls and subprocessors; a termination and handover package.
- SLOs with measurement definitions and sample telemetry exports.
- Integration ownership: who will maintain adapters; compatibility and rollback clauses.
- Handover deliverables: code, schemas, logs, runbooks, test suites.
Operational and security audits
Require vendor evidence of operational controls: penetration test summaries, third-party audits (if available), security posture questionnaires, and a regular audit cadence. Specify remote-support controls and just-in-time access methods; do not accept blanket remote admin rights without access governance.
- Subprocessor disclosures and an approval process.
- Defined remote-support channels with time-limited access and logging.
- Right-to-audit clauses and remediation plans.
Commercial terms tied to SLOs
Include credits, remediation obligations, and funding holdbacks linked to SLO breaches. Also require cooperation on decommissioning tasks and transfer of assets. Avoid very long exclusive terms without exit and handover guarantees.
- Funding tranches released on passing SLO gates.
- Remediation SLAs and financial credits for missed SLOs.
- Handover support hours and a defined transition window in termination.
Related Peak Demand resources
Industry and AI sources reviewed
- Artificial Intelligence Risk Management Framework (AI RMF 1.0)National Institute of Standards and Technology (NIST)
- AI Risk Management Framework: Generative AI ProfileNational Institute of Standards and Technology (NIST)
- OECD AI PrinciplesOrganisation for Economic Co-operation and Development
Privacy, telecommunications, recording-consent, cybersecurity, consumer-protection, employment, and records obligations vary by jurisdiction and use case. This article is operational guidance, not legal advice; organizations should confirm applicable requirements with qualified professionals.
Frequently asked questions
A serious managed service should include discovery, workflow design, telephony, integrations, validation rules, testing, monitoring, human escalation, incident handling, change control, analytics, and ongoing optimization. The value is the complete operating system around the model, not access to a model alone.
Official reference: Artificial Intelligence Risk Management Framework (AI RMF 1.0)
The operating model should assign clear owners for telephony, prompts, knowledge, APIs, credentials, incident response, analytics, approvals, and release management. Enterprise buyers should avoid deployments where those responsibilities are ambiguous or split across vendors without accountability.
Official reference: Artificial Intelligence Risk Management Framework (AI RMF 1.0)
Evaluate the complete workflow under realistic volume, latency, interruption, transfer, integration, and failure conditions. Measure task completion, escalation quality, unsupported responses, system errors, recovery behavior, and how quickly operators can detect and correct problems.
Official reference: Artificial Intelligence Risk Management Framework (AI RMF 1.0)
Ask for documented use-case boundaries, data handling, access controls, model and prompt change management, evaluation procedures, audit logs, human-oversight rules, incident response, subcontractor dependencies, and a process for reviewing material system changes.
Official reference: Artificial Intelligence Risk Management Framework (AI RMF 1.0)
Need deeper enterprise Voice AI integration?
For custom APIs, SIP and telephony architecture, multi-system workflows, QA, observability, and enterprise deployment, Peak Demand commonly evaluates platforms such as Retell AI as part of a managed architecture.
Explore Retell for Enterprise Voice AIPeak Demand may earn a commission from this link.


