How LLMs Decide Which Sources to Cite and Retrieve
A practical guide for marketing leaders and SEO teams explaining how large language models select, retrieve, and cite web sources — and what organizations can actually control to improve their chances of being retrieved and used in AI-driven answer surfaces.
Short answer — how LLMs choose sources
Large language models used in search and answer engines generally work as a two‑stage system: a retrieval layer pulls candidate content that matches the query, then a generative or grounding layer synthesizes an answer and attaches citations. Retrieval uses keyword, semantic, and embedding signals; grounding uses document-level metadata, explicit entity matches, perceived authority, and policies to decide which retrieved sources to surface and cite. You can influence these signals, but you cannot guarantee a specific.
Retrieval then grounding — the pipeline
In practice the system first reduces the web to a shortlist of candidate documents using search indexes, embeddings (vector representations), or traditional text matching. The generative model then uses those candidates as context to produce an answer and decide which sources to reference. Improving your chances means improving both the probability your pages are retrieved and their score during grounding.
- Retrieval: signal-matching (BM25, dense vectors), indexes, URL metadata.
- Grounding: content relevance, entity alignment, citation policies, and freshness.
- Result format: exact quote, paraphrase, or provenance link — policies and UI determine if a source is shown as a citation.
What this means for visibility
Focus on making pages discoverable (indexable, embedded, and identifiable as an entity source) and clearly authoritative (unique, well-sourced, and linked). Work the whole stack: entity modelling, topical coverage, technical SEO, structured data, and off‑site signals.
- Controlable: content structure, schema markup, canonicalization, internal linking, and distribution.
- Influential but uncontrolled: how a platform chooses to display citations, citation wording, or whether AI overviews will mention your site.
Core definitions every leader should know
Define terms precisely so strategy and operations align across SEO, content, and engineering.
AEO, GEO, entities, and retrieval
AEO (Answer Engine Optimization) and GEO (Generative Engine Optimization) are practical disciplines focused on improving the likelihood that automated answer surfaces will select and cite your content. An entity is a discrete real‑world thing (person, organization, product, concept) that search engines identify and connect across pages. Retrieval is the process of finding candidate documents for a query (using keyword, semantic, and embedding methods).
- AEO/GEO: optimize pages for machine-driven answer selection, not just classical SERP rankings.
- Entities: canonical representations that reduce ambiguity (use consistent names, identifiers, and structured data).
- Retrieval: reduces billions of pages to a shortlist a model can reason over.
Structured data, knowledge graphs, and citations
Structured data (schema markup) exposes machine-readable facts about pages and entities. Knowledge graphs aggregate entity facts and link them to canonical sources. Citations in an AI answer are provenance markers that tie a generated claim to one or more source documents.
- Use schema to make entity facts explicit for crawlers and downstream AI features.
- Knowledge graphs help engines disambiguate entities and rank authoritative sources.
Signals that affect retrieval and citation
Not every signal has equal weight in both stages. Below, separate the most operationally relevant signals and where to focus investment.
Content signals — topical fit, clarity, and entity alignment
LLMs and retrieval systems prioritise content that clearly answers an intent and maps to an entity model. Well‑structured, comprehensive content that uses consistent entity labels, factual support, and unique perspectives is more likely to become a candidate and to be trusted during grounding.
- Topical depth and unique information increase relevance for embeddings and semantic matching.
- Clear entity mentions and disambiguating context (dates, official names, identifiers) make grounding easier.
- Human-first useful content aligns with documented guidance for quality: write for users first.
Technical signals — indexability, schema, and metadata
Indexability and schema markup make pages visible and machine-readable. Ensure canonical URLs, crawlable content, relevant metadata, and schema that exposes entity relationships and provenance. These technical signals are low-cost but high-leverage for both retrieval and citation.
- Canonicalization, sitemaps and crawlable HTML are prerequisites for being considered at all.
- Schema.org types and properties (Organization, WebPage, Article, Product) help map pages to knowledge graphs.
- Machine‑readable timestamps, authorship, and licensing can influence freshness and trust signals.
Authority signals — links, brand, and first-party data
External links, brand trust, and first‑party referenceability (e.g., official records, published datasets) matter during grounding. LLMs often prefer primary or authoritative sources for factual claims; that preference is an engineering choice and platform policy, not an SEO guarantee.
- Backlinks and brand queries support perceived authority but do not deterministically create citations.
- Primary sources and official pages are prioritized when facts must be verified — invest in being the source of record where possible.
- Distribution and amplification (press, scholarly citation, datasets) increase the chance of retrieval.
Operational architecture: turn understanding into a system
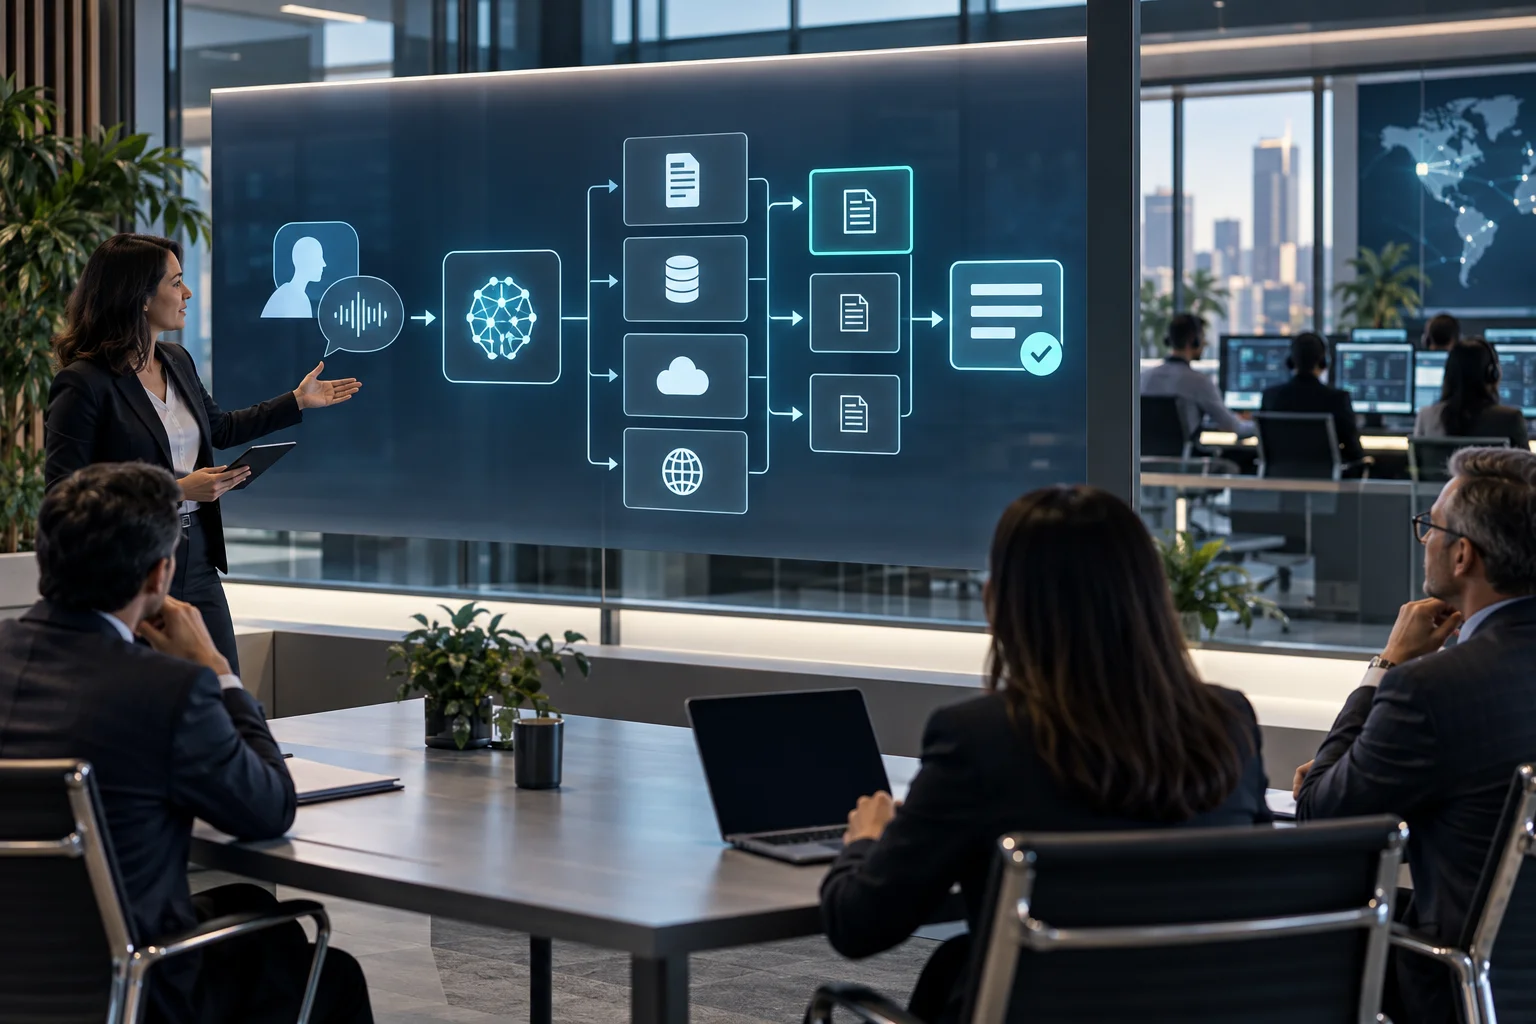
Peak Demand recommends a simple operating model you can realistically implement: Research & entity model → topic & page graph → authoritative content → structured data & internal linking → distribution → measurement.
Research and entity model → topic & page graph
Start with an entity inventory: list canonical entities your organisation owns or serves (products, services, standards, people). Map those to search intents and build a topic-to-page graph so each canonical entity has a clear canonical page and supporting spoke pages. This reduces ambiguity at retrieval time and creates high‑quality candidates for grounding.
- Inventory entities and preferred names/identifiers.
- Map queries and intents to a canonical page for each entity.
- Use hub-and-spoke content to capture related subtopics and FAQs.
Authoritative content, structured data, and internal linking
Produce content that serves the user but is engineered for discoverability: clean HTML, consistent metadata, schema markup that encodes entity relationships, and an internal linking structure that signals the canonical source for facts. Structured data is not a citation guarantee, but it helps machines parse and reason about facts.
- Prioritise canonical pages for entity facts and provide supporting references.
- Implement schema to mark the canonical entity, authorship, publication date, and licensing where relevant.
- Use internal linking to point evidence and authority at canonical pages.
Distribution, brand signals and governance
Distribution increases the probability of retrieval. Coordinate PR, developer docs, datasets, and partner citations to create off‑site signals. Layer governance so any data, policy, or legal constraints about provenance are tracked. For enterprise deployments with regulatory needs, involve compliance early.
- Amplify canonical content through owned channels, partners, and datasets.
- Track provenance and access controls for sensitive content; do not publish restricted facts publicly.
- If you need assisted implementation, contact Peak Demand to discuss integration and governance.
What search engines document vs. industry inference
Distinguish documented guidance from reasonable practitioner inference — this keeps expectations aligned with documented behaviour.
Documented guidance
Google publishes clear guidance on making content indexable, building helpful content, and using structured data for better machine understanding. Those documents are the operational baseline for any visibility program and should shape your technical and content priorities.
- Indexability, canonicalisation, and crawlability are documented fundamentals.
- Google's helpful content guidance emphasises people-first, reliable content.
- Google documents how structured data works and provides types and examples for common use cases.
Practitioner inference and measured observations
Practitioners have observed retrieval using dense embeddings, entity matching, and grounding preferences for primary sources. These are sensible operational assumptions backed by experiments, but they are not guarantees. Treat them as hypotheses to test in your environment.
- Inference: embeddings increase semantic matching for long-tail or conversational queries.
- Inference: canonical, well-linked entity pages are more likely to be cited as provenance.
- Action: run controlled experiments to see what improves retrieval for your queries.
Measure, test, iterate — practical KPIs and experiments
Visibility in AI search is measurable. Define the right KPIs and run focused experiments with clear hypotheses.
KPIs to prioritise
Measure both classical SEO metrics and AEO/GEO‑specific signals. Combine them into a dashboard for visibility and provenance outcomes.
- Index coverage, crawl frequency, and canonical mapping.
- SERP impressions and click-through rates for queries mapped to entities.
- Answer-box or featured snippet impressions (where available) and referral traffic from those features.
- Entity mentions and knowledge panel changes (where trackable).
- Controlled retrieval tests: promo changes to schema or content and measurement of candidate retrieval rates.
Example experiments
Run small, auditable changes and measure downstream effects. Isolate variables: schema only, schema + content, internal linking changes, or distribution signals.
- A/B test schema additions on matched pages and track impressions for target queries.
- Publish a clarifying canonical page for an entity and measure shifts in referring traffic and branded query behavior.
- Use dataset publication or partner references to test if off-site citations influence retrieval for specific factual claims.
Related Peak Demand resources
Industry and AI sources reviewed
- Schema.org DocumentationSchema.org
- Understand how structured data worksGoogle Search Central
- Creating helpful, reliable, people-first contentGoogle Search Central
- SEO Starter GuideGoogle Search Central
- AI features and your websiteGoogle Search Central
Search-engine and AI-answer behavior changes over time. Google documentation can establish published requirements and guidance, but inclusion in rankings, AI Overviews, citations, or LLM answers is never guaranteed. Practitioner observations should be labelled as inference or testing rather than official ranking factors. This article is operational guidance, not legal advice; organizations should confirm applicable requirements with qualified professionals.
Frequently asked questions
SEO improves visibility in traditional search results. AEO focuses on making content easy for answer systems to extract and use. GEO focuses on visibility in generative search and AI answer experiences. In practice, the strongest strategy combines technical accessibility, useful content, clear entities, strong internal relationships, structured data, and credible source authority rather than treating them as isolated channels.
Official reference: SEO Starter Guide
No. Structured data can make page entities and relationships more explicit and can support eligible search features, but it does not guarantee rankings, AI Overview inclusion, citations, or mentions in generative answers. It should reinforce accurate visible content rather than replace it.
Official reference: Understand how structured data works
Search and answer systems need to understand what a brand, person, product, service, or concept is and how it relates to other entities. Consistent naming, authoritative pages, structured relationships, internal linking, and corroborating references can reduce ambiguity and make a site easier to interpret and retrieve.
Official reference: Schema.org Documentation
Track traditional search visibility alongside query coverage, indexed pages, non-brand discovery, AI referral traffic where available, observed citations or mentions, entity consistency, content-cluster coverage, internal-link depth, and lead quality. Treat AI-surface monitoring as directional because answer composition can vary by model, query, user, and time.
Official reference: AI features and your website
Build a search and AI visibility system that compounds
Peak Demand connects technical SEO, entity architecture, knowledge graphs, structured data, topical authority, internal linking, distribution, and measurement into a managed SEO/AEO/GEO operating system.
Explore Peak Demand AI SEO, AEO & GEO


