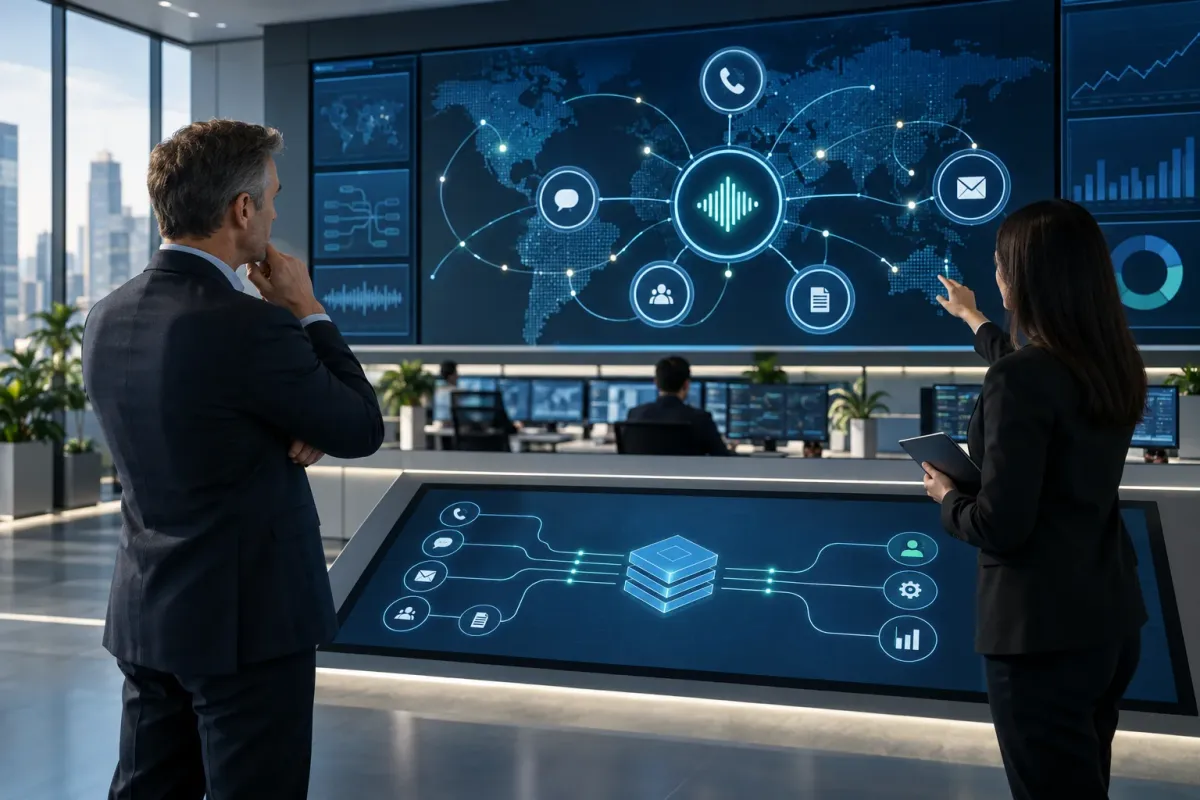
Cross‑Channel Orchestration Fabric for Enterprise Voice AI: Real‑Time Decisioning
A pragmatic guide for enterprise buyers and architects on building or procuring a cross-channel orchestration fabric that enables secure, auditable, and reliable real‑time decisioning for Voice AI at scale. Covers architecture, managed‑service boundaries, governance, data controls, failure modes, and procurement criteria.
1. Why a dedicated orchestration fabric matters
Enterprises move beyond point AI features when Voice AI must operate across channels, systems, and regulated decision domains. A dedicated orchestration fabric is the runtime and control plane that ensures consistent, auditable, and safe real‑time decisioning.
Role and responsibilities
The orchestration fabric is not the speech model or the CRM. It is the intermediary that governs intent routing, policy enforcement, data minimization, API mediation, and human handoff. In operational terms it performs: intent normalization, decisioning against business rules, push/pull to approved enterprise systems, stateful session management, and generation of auditable records.
- Intent normalization: unify voice intents with web/chat channels for omnichannel context.
- Policy enforcement: apply throttles, verification rules, and risk controls before any back‑end change.
- Approved integrations: expose only controlled adapters to systems of record (CRM, billing, order management).
- Session state and rollback: track transaction state with a versioned ledger to support rollback or replay.
The canonical interaction flow
Design the orchestration with this canonical flow and explicit handoffs: Caller → Voice AI (ASR/LM/NLP) → business‑rules layer (orchestration fabric) → approved enterprise systems → response, transaction, or human handoff → QA and analytics. Each arrow is a control boundary: define access level, audit expectations, latency budget, and failure action at every boundary.
- Caller: session identification, consent capture, and initial triage.
- Voice AI: speech recognition and candidate intents returned as structured payloads.
- Business‑rules layer: deterministic decisioning, enrichments, and API calls to enterprise systems.
- Enterprise systems: read/write operations occur only via controlled adapters with explicit approvals.
- QA and analytics: store call transcripts, decision audit trails, and quality metrics for sampling.
2. Core architecture and integration patterns
Architectural choices determine what you can control, audit, and scale. Below are the practical components and the integration patterns buyers must specify.
Ingress, voice AI, and session management
Ingress captures caller metadata and consent, routes audio to the Voice AI stack, and returns structured candidate intents. Session management is stateful: transactions, timers, and idempotency tokens must persist in the fabric to enable retries and reconciliation.
- Ingress: SIP / WebRTC front door with secure TLS and caller verification hooks.
- Voice AI: model outputs are treated as telemetry — deterministic logic in the fabric transforms them into decisions.
- Session state: durable stores with transactional semantics (session id, step index, tentative changes).
Business rules and logic bridges
The business‑rules layer is where policy, pricing, entitlements, fraud signals, and voice analytics converge. Implement logic bridges: thin adapters that convert fabric requests to approved API calls to CRM, billing, or order systems. Differentiate read-only lookups from state-mutating operations and gate the latter with approvals.
- Logic bridges: adapter layer with schema validation and rate‑limiting.
- Read vs write gates: two-phase commits, change tickets, or human confirmation before state modifications.
- Enrichment: incorporate real‑time risk signals (device, velocity, account flags) before authorising actions.
Adapters, approved APIs, and system ownership
Adapters must be scoped and approved by system owners. The fabric should never directly embed credentials for multiple systems; use vaulting, short‑lived tokens, and centralized access approvals. Define ownership: which team owns each adapter, who can change mappings, and who audits logs.
- Approved APIs only: deny all else by default; use allow‑lists and an adapter registry.
- Credential management: short‑lived tokens, hardware security modules, and key rotation policies.
- Change control: configuration changes to adapters pass through versioned change management.
3. Managed service and operating model options
Buying a managed orchestration fabric requires precise scoping of responsibilities, access, and performance expectations. Avoid fuzzy ‘fully managed’ statements—define boundaries in the contract.
Service scopes: shared, dedicated, or hybrid
Providers typically offer shared multi‑tenant fabrics, dedicated instances, or hybrids. Choose based on data residency, performance isolation, and integration complexity. Dedicated or customer‑colocated fabrics reduce blast radius for sensitive integrations but increase cost and operational complexity.
- Shared fabric: faster onboarding, lower cost, but limited control over infrastructure and subprocessors.
- Dedicated fabric: customer-controlled infra, stronger isolation, greater integration flexibility.
- Hybrid: control plane in provider network, runtime adapters in customer environment for sensitive systems.
Operational responsibilities matrix
Create a RACI-style matrix covering: adapter maintenance, schema changes, escalation, observability, patching, backups, and incident response. Specify remote-support access mechanisms, subprocessors, and approval workflows for any code that runs in your environment.
- RACI: clearly assign responsibility for each adapter and for changes to business rules.
- Remote access: define jump-hosts, change windows, and approval logs for vendor technicians.
- Subprocessors: require an approved list and timely notice for additions or changes.
Peak Demand differentiation: implementation and optimization
Peak Demand typically combines custom infrastructure, logic bridges, QA scaffolding, and managed optimization to reduce integration risk. Expect vendor-delivered artifacts: adapter templates, test harnesses, observability dashboards, and continuous improvement cycles based on sampled QA.
- Custom infrastructure and logic bridges reduce integration rework.
- System integrations are delivered with test suites and continuous QA sampling.
- Managed optimization: vendor-run experiments with pre-agreed guardrails and rollback plans.
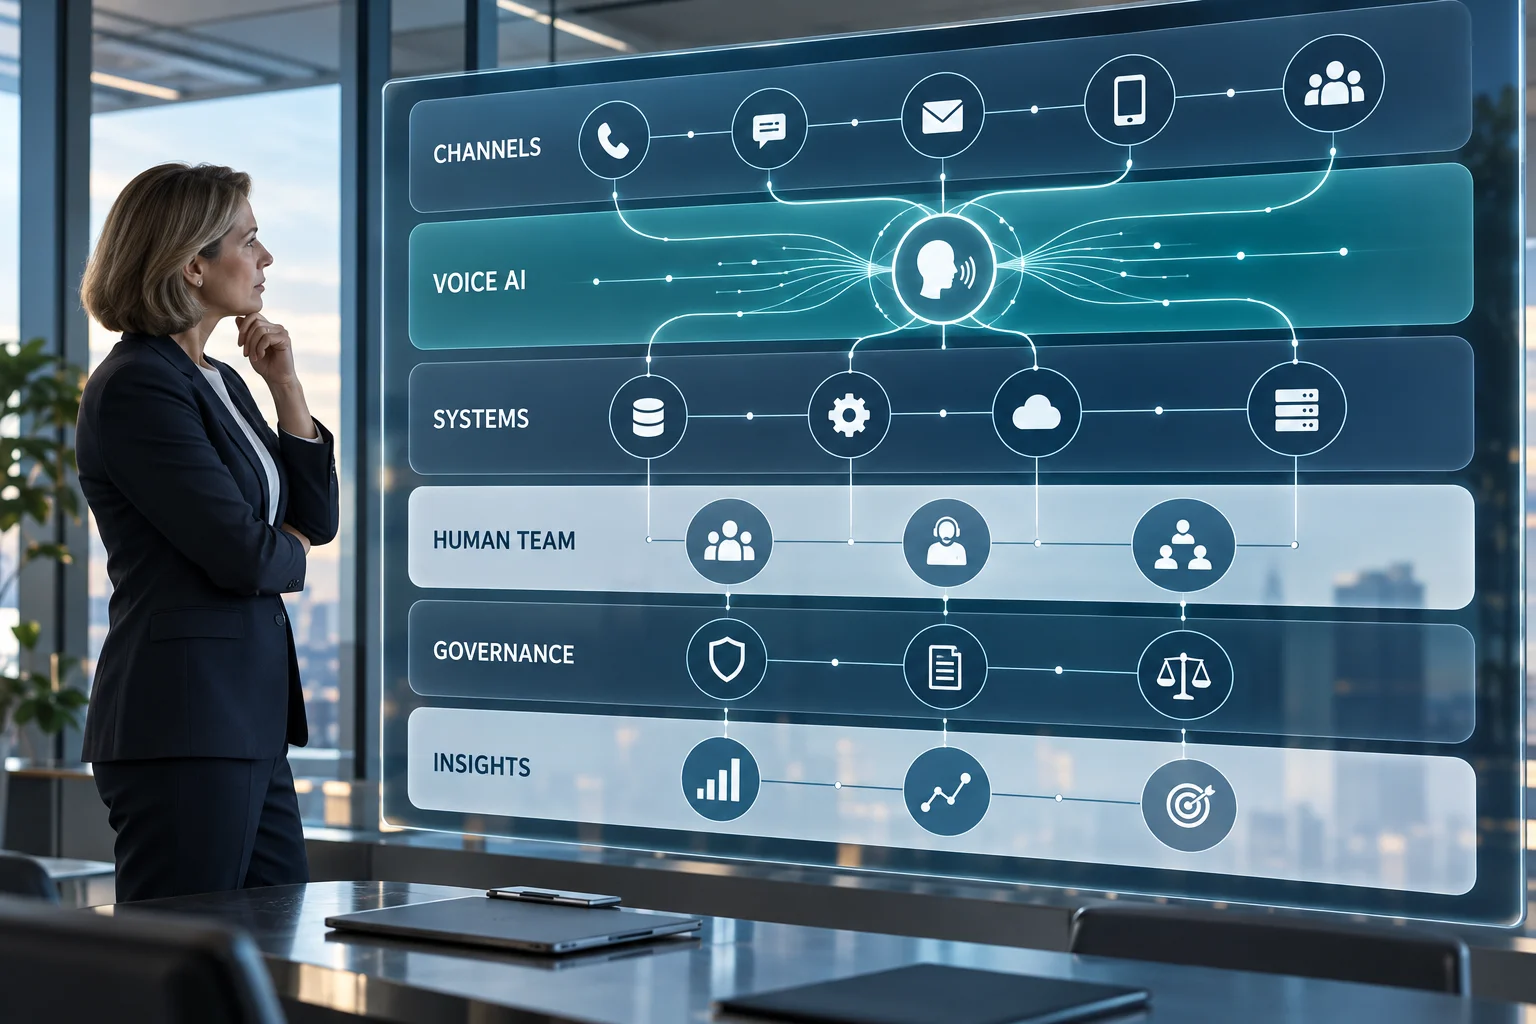
4. Governance, auditability and human oversight
Regulated and large enterprises need auditable governance and explicit human oversight. These are implementation-first requirements, not optional features.
Human-in-the-loop and escalation controls
Keep high‑risk decisions (refunds, account closures, service suspensions, legal statements) behind human authorization. The fabric should provide clear escalation triggers, pre-filled context, and the ability to pause, review, and approve or abort transactions.
- Escalation triggers: confidence thresholds, sensitive intent labels, or mismatch with transactional policies.
- Human tools: case context, transcript snippet, decision reason codes, and one-click approve/deny.
- Audit trail: every human action must be logged with who, when, why, and what changed.
Audit logs and traceability
Require immutable, tamper‑evident logs for transcripts, decision inputs, adapter calls, configuration changes, and operator actions. Logs must support reconstruction: replaying a session end‑to‑end for QA or regulator review.
- Trace IDs across components for end‑to‑end session reconstruction.
- Record both model outputs and deterministic logic decisions; do not rely on model explainability alone for audit.
- Retention and export: contractually defined retention windows and secure export mechanisms.
Operationalizing change control and QA
Introduce change gates: staging, approval, canary, and rollback. Pair releases with measurable KPIs (intent accuracy, escalation rate, false positives) and sample human QA for drift detection. Maintain a documented change log tied to deployment artifacts.
- Staged rollout with traffic caps and error budgets.
- Automated regression suites and sampled human QA for production verifications.
- Configuration as code for logic rules with git-backed change history.
5. Reliability, observability and failure boundaries
Predictable behaviour under failure is critical for customer trust. Design the fabric for transparent failures and rapid human recovery.
Defined failure modes and fallbacks
Document explicit failure modes (ASR drop, model timeout, adapter error, system outage) and their immediate actions: retry, degrade to read-only, transfer to human, or play safe response. Map each mode to a human-run runbook.
- ASR/model timeout: play a short holding prompt, attempt a single retry, then route to agent.
- Adapter write failure: abort commit, mark session for reconciliation, escalate if transaction was in-flight.
- Service-wide outage: degrade to scripted IVR or agent-only routing.
Observability and SLAs
Require end-to-end observability: request/response tracing, per-step latency histograms, and business metrics (successful transactions, escalation rates, recontact rate). Use these to create measurable SLAs (latency SLOs, transaction success rate, mean time to human handoff).
- Trace-level telemetry with correlated IDs across voice AI, fabric, and adapters.
- Business SLOs tied to contract penalties and remediation steps.
- Dashboards for operations, QA samplers, and monthly executive summaries.
Testing, chaos, and staged release practices
Emulate adverse conditions in isolated testbeds: network latency, adapter failures, and degraded voice models. Run chaos experiments on non-production fabrics and require canary rollouts with real user traffic caps.
- Non-production testbeds that mirror production adapters and policies.
- Canary traffic percentages and automated rollback thresholds.
- Regular load testing for peak call scenarios and system resilience.
6. Data residency, privacy and security boundaries
Data controls must be explicit: hosting region, backup geography, processor lists, transfer mechanisms, and remote support access. Confirm obligations with legal and data protection professionals for your jurisdictions.
Residency, transfer and subprocessors
Specify hosting and backup regions, subprocessors, and any cross‑border transfer mechanisms. Vendors should provide a subprocessor list, notification windows, and contractual controls for onward transfer and retention.
- Define primary hosting region and secondary backup region in the contract.
- Require timely notification and approval for new subprocessors and changes to their locations.
- Explicitly state mechanisms for cross‑border transfer (standard contractual clauses, adequacy, etc.) and verify with legal counsel.
Recording, consent and retention
Make recording and transcript retention policies explicit. Capture consent at call ingress when recordings or profile enrichment occur. Define retention periods for recordings and logs, exportability, and secure deletion procedures.
- Consent capture: explicit opt-in and clear prompts before recording or PII capture.
- Retention windows: contractually agreed and auditable deletion or archival processes.
- Data minimization: only store fields required for audit or transaction reconciliation.
Access controls and remote support
Limit vendor remote access via documented mechanisms. Use least privilege for service accounts, MFA for operator access, and logged temporary elevation. Outline breach notification timelines and responsibilities in the agreement.
- Temporary remote sessions with recorded approvals and time-bound credentials.
- Least-privilege service identities and vault-backed secrets.
- Defined breach notification timelines, roles, and remediation responsibilities—confirm with legal.
Related Peak Demand resources
Industry and AI sources reviewed
- Artificial Intelligence Risk Management Framework (AI RMF 1.0)National Institute of Standards and Technology (NIST)
- OECD AI PrinciplesOrganisation for Economic Co-operation and Development
- AI Risk Management Framework: Generative AI ProfileNational Institute of Standards and Technology (NIST)
Privacy, telecommunications, recording-consent, cybersecurity, consumer-protection, employment, and records obligations vary by jurisdiction and use case. This article is operational guidance, not legal advice; organizations should confirm applicable requirements with qualified professionals.
Frequently asked questions
A serious managed service should include discovery, workflow design, telephony, integrations, validation rules, testing, monitoring, human escalation, incident handling, change control, analytics, and ongoing optimization. The value is the complete operating system around the model, not access to a model alone.
Official reference: Artificial Intelligence Risk Management Framework (AI RMF 1.0)
The operating model should assign clear owners for telephony, prompts, knowledge, APIs, credentials, incident response, analytics, approvals, and release management. Enterprise buyers should avoid deployments where those responsibilities are ambiguous or split across vendors without accountability.
Official reference: Artificial Intelligence Risk Management Framework (AI RMF 1.0)
Evaluate the complete workflow under realistic volume, latency, interruption, transfer, integration, and failure conditions. Measure task completion, escalation quality, unsupported responses, system errors, recovery behavior, and how quickly operators can detect and correct problems.
Official reference: Artificial Intelligence Risk Management Framework (AI RMF 1.0)
Ask for documented use-case boundaries, data handling, access controls, model and prompt change management, evaluation procedures, audit logs, human-oversight rules, incident response, subcontractor dependencies, and a process for reviewing material system changes.
Official reference: Artificial Intelligence Risk Management Framework (AI RMF 1.0)
Need deeper enterprise Voice AI integration?
For custom APIs, SIP and telephony architecture, multi-system workflows, QA, observability, and enterprise deployment, Peak Demand commonly evaluates platforms such as Retell AI as part of a managed architecture.
Explore Retell for Enterprise Voice AIPeak Demand may earn a commission from this link.


